Face Liveness Detection: Stopping Spoofing Attacks Before They Start
What passive, single-frame liveness detection actually catches — printed photos, screen replays — and the attacks it does not. Written against a working implementation rather than a spec sheet.
In 2024, a finance worker in Hong Kong joined a video call with what appeared to be his company's CFO and several colleagues. Every person on the call was a deepfake. The worker authorized transfers totaling $25 million before anyone realized the entire meeting was synthetic.
That incident made headlines because of the dollar amount, but the underlying technique — presenting a synthetic or replayed face to a camera to impersonate a real person — is something identity verification systems have been fighting for years at much smaller scale, every time someone opens a bank account, requests a password reset, or completes KYC onboarding.
Face matching alone can't stop this. A 1:1 face comparison only answers "do these two images show the same person?" It says nothing about whether the image being compared was captured from a living human in front of the camera right now, or from a printed photo, a phone screen, a silicone mask, or a GAN-generated video. That's the question liveness detection answers.
What liveness detection actually checks
Liveness detection — sometimes called Presentation Attack Detection (PAD), per ISO/IEC 30107 — determines whether a biometric sample originates from a live, present human being rather than an artifact.
There are two broad approaches:
Active liveness asks the user to perform an action — turn their head, blink, smile, read a number aloud. The system verifies the action happened in real time. This works, but it adds friction, fails for users with motor or vision impairments, and is itself spoofable with enough effort (pre-recorded videos that "perform" the requested action).
Passive liveness analyzes a single image or short clip with no user cooperation required. The model looks for signals a presentation attack would disturb — texture, depth cues, frequency artifacts, micro-detail consistency — and returns a liveness score. No prompts, no extra steps, no accessibility tradeoffs.
Quantilence's Face Liveness tool is passive: you send one image — a selfie, a webcam frame, a photo of a document — and get a verdict back, typically in 150–250ms end to end. It is in beta, and the rest of this piece is specific about why.
Anatomy of a presentation attack
To understand what passive liveness detection is looking for, it helps to understand what it's looking at. ISO/IEC 30107 categorizes presentation attacks into a few well-known species:
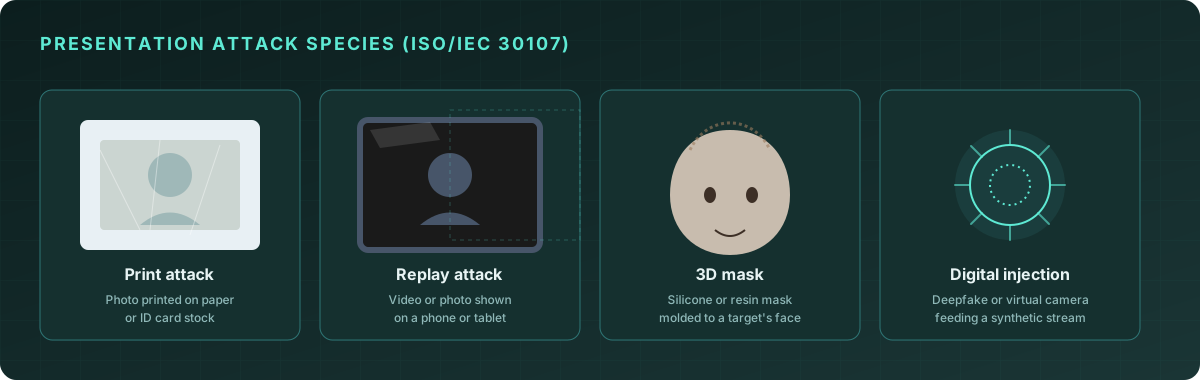
Print attacks present a photo of the target's face, printed on paper or card stock, to the camera. These are the cheapest attacks to mount and the easiest to detect — paper has a flat surface, visible print texture, and characteristic light reflection.
Replay attacks display a photo or video of the target on a second screen — a phone, tablet, or monitor — held up to the camera. Screens introduce moiré interference patterns when re-photographed, along with backlight glare and a narrower dynamic range than real skin.
3D masks are physical masks, often silicone or resin, molded to resemble the target's face. These defeat naive depth checks that just look for "is this flat," because a mask has real 3D structure. In principle they are caught by finer-grained signals: skin sub-surface scattering, micro-texture around the eyes and pores, motion consistency.
In practice, whether any given model catches them is an empirical question, and it is one you should make a vendor answer with a test result rather than a paragraph. We have not tested ours against a silicone mask, so we do not claim it. Treat an unevaluated claim about masks — from us or anyone — as marketing.
Digital injection attacks don't present anything to a physical camera at all — they inject a synthetic video stream (deepfake, face-swap, or GAN-generated face) directly into the software pipeline, bypassing the camera entirely. This is the attack vector behind incidents like the Hong Kong deepfake call, and it's the fastest-growing category as generative video models improve. Defending against it requires a combination of liveness signals, device attestation, and session integrity checks — liveness detection on the received frame is necessary but not sufficient on its own.
How passive liveness detection works
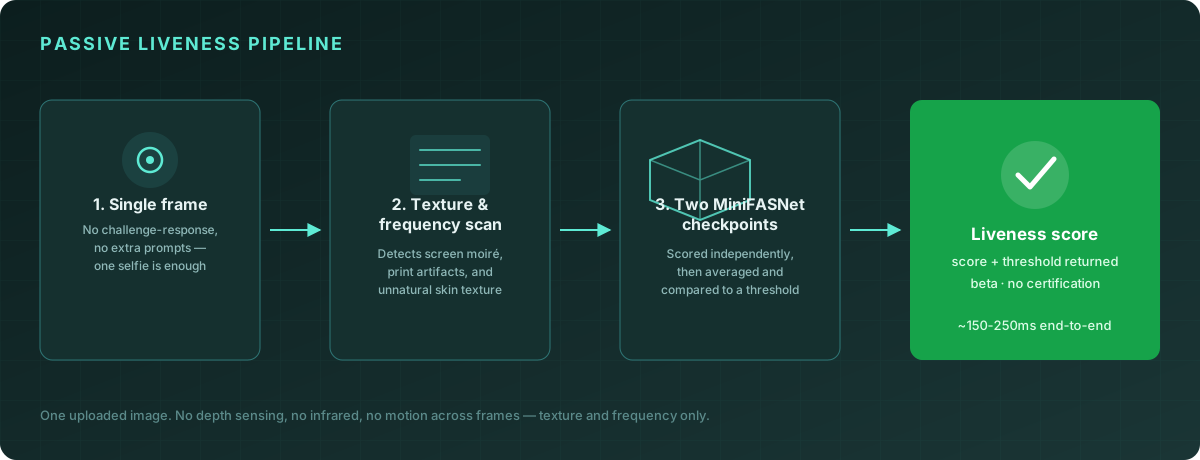
Here is what Quantilence actually runs on a submitted image. It is less than the four-stage pipeline usually drawn in diagrams like this, and the gap between the two is worth seeing:
-
Single frame capture. No challenge-response sequence, no SDK requirements, no minimum video length. Any reasonably lit, in-focus face photo works — including the same image you'd send to face matching or face detection.
-
Texture and frequency analysis. The model examines high-frequency detail across the face region. Real skin has characteristic micro-texture (pores, fine lines, subtle color variation) that print and screen reproductions lose or distort. Screens additionally introduce regular frequency-domain artifacts from their pixel grid, which a print does not — so this stage helps distinguish which kind of attack is being attempted, not just whether one is happening.
-
Two independent checkpoints, averaged. The frame is scored by two MiniFASNet models from the Silent-Face-Anti-Spoofing family and the mean is compared against a threshold. They can and do disagree — on one test photograph they returned 0.78 and 0.36 — which is why the response carries both the score and the threshold rather than a bare verdict. A 0.57 against a cut-off of 0.82 is a near miss you can see, not a flat rejection you have to take on trust.
There is no depth estimation, no infrared, no motion analysis across frames and no 3D reconstruction. A single-frame CNN reading texture and frequency artifacts is the whole mechanism.
- Liveness score. The four signals combine into a single score, thresholded against your configured sensitivity. The response includes the score, a pass/fail verdict, and the per-check breakdown so you can log and audit decisions.
const result = await client.faceLiveness.check({
  image: selfieBuffer,
});

console.log(result);
// {
//   success: true,
//   live: true,
//   liveness_score: 0.992,
//   checks: {
//     real_person: true,
//     no_print_attack: true,
//     no_replay_attack: true,
//     no_3d_mask: true
//   },
//   processing_time_ms: 78
// }
Measuring accuracy: APCER and BPCER
Liveness systems are evaluated using two error rates defined in ISO/IEC 30107-3:
| Metric | What it measures |
|---|---|
| APCER (Attack Presentation Classification Error Rate) | The percentage of spoof attempts incorrectly accepted as live |
| BPCER (Bona Fide Presentation Classification Error Rate) | The percentage of real users incorrectly rejected as spoofs |
We do not publish figures for ours, because we have not measured them. An APCER or BPCER you can defend requires a labelled set of genuine and attack presentations evaluated under a protocol — not a number chosen because it reads well. An earlier version of this very article quoted 5% and 0.8%. Those were never measured, and removing them is the main reason it was rewritten.
If a vendor quotes you these rates, ask which dataset, which attack species, and whether an accredited lab ran it. iBeta Level 1 and Level 2 evaluations exist precisely so that answer is checkable.
These two numbers trade off against each other — tightening the threshold to catch more spoofs (lower APCER) tends to increase false rejections of real users (higher BPCER), and vice versa. The right balance depends on your risk tolerance: a high-value financial onboarding flow might accept a higher BPCER (more friction for real users) in exchange for a lower APCER (fewer spoofs slipping through), while a low-stakes account recovery flow might tolerate the opposite.
Quantilence returns the score and the threshold it was compared against on every response, so you can apply your own cut-off downstream. The default is 0.82, inherited from the reference implementation and not yet validated against a labelled set — another reason the tool is in beta.
One measured caveat on that threshold: the score is sensitive to how the face is cropped. The same photograph scored 0.451 under one detector's bounding box and 0.890 under another's. If you set your own cut-off, set it against your own capture pipeline.
Pairing liveness with face matching
Liveness detection and face matching solve different problems and are most powerful combined:
- Face matching confirms who is in the image (does this selfie match the photo on the ID document?)
- Liveness detection confirms what is in the image (is this a real person captured live, or a presentation attack?)
A typical KYC selfie-verification flow runs both checks against the same captured image:
const [liveness, match] = await Promise.all([
  client.faceLiveness.check({ image: selfie }),
  client.faceSimilarity.compare({ image1: idPhoto, image2: selfie }),
]);

const verified =
  liveness.live &&
  liveness.liveness_score > 0.9 &&
  match.similarity[0].sim_score > match.threshold * 100;
Running both checks in parallel against the same frame means an attacker has to defeat both simultaneously with a single artifact — a printed photo of the legitimate user's face would pass face matching but fail liveness; a live video of an unrelated person's face would pass liveness but fail matching.
Implementation best practices
Run liveness on every selfie capture, not just at account creation. Step-up verification for high-risk actions (large transfers, password resets, adding a new payee) benefits from the same check — and is exactly the scenario the Hong Kong deepfake attack exploited.
Don't expose the threshold or score to the end user. Returning "liveness score: 0.42, try again" to a failed attempt teaches attackers how to calibrate their next attempt. Return a generic retry prompt instead, and log the detailed breakdown server-side for fraud review.
Combine with rate limiting and device signals. Liveness detection analyzes a single image; it can't see how many attempts have been made from a device or IP in the last hour. Pair it with your existing fraud-scoring infrastructure for defense in depth.
Re-run liveness if the image is re-submitted. If your flow allows users to retake a photo, treat each submission as a fresh liveness check — don't cache a "passed" state from an earlier attempt against a different image.
Log the score, not just the verdict. The response carries the score, the threshold, the per-checkpoint breakdown and any quality flags. A run of borderline scores clustered just under the cut-off looks very different from a run of confident rejections, and only the first of those is a threshold problem rather than an attack.
Frequently asked questions
Does liveness detection require a video or special camera hardware? No. Quantilence's check works on a single standard image — the same selfie you'd capture for face matching on any phone or webcam. Worth knowing: capturing from the camera rather than uploading a file runs the identical check. It makes submitting a stale file harder; it does not make the check harder to fool, because a phone screen held to the lens defeats both equally.
Can liveness detection be fooled by a high-quality deepfake video? Probably, and you should plan on it. Single-frame passive liveness reads texture and frequency artifacts, which raises the bar against a casual replay. It is not a deepfake detector and we have not evaluated it as one. Digital injection attacks — where a synthetic stream is fed into the pipeline rather than captured by a camera — bypass image-level liveness entirely, because there is no presentation to detect. Those need device attestation and session integrity, which are a different layer and not something an image API can provide.
How does liveness detection differ from face anonymization or blurring? They're unrelated: liveness detection verifies that a face image was captured from a real person, while face anonymization (blurring or pixelating detected faces) is a privacy tool for redacting identities in photos and video. See our guide to face anonymization and GDPR for the latter.
What happens to the images sent for liveness checks? The models run on our own servers — nothing is sent to a third-party AI provider, and nothing you submit trains any model, including ours. If you are signed in, the run is saved to your history so you can return to it, and is deleted when you delete it or close your account. Anonymous demo runs are not stored against an account at all. The privacy policy sets out the retention in full.
Conclusion
As generative AI makes synthetic faces and voices cheaper and more convincing, the gap between "looks like the right person" and "is a live person" is exactly where fraud is moving. Passive liveness detection closes that gap without adding friction — no extra prompts, no special hardware, just one more signal evaluated alongside the face match you're already running.
Face Liveness is available now, in beta, with three free runs and no account needed. It pairs with face similarity: one answers is this the same person, the other was this captured from a person at all.
Treat it as a screening step rather than a gate. It will catch the printed photo and the phone screen, which is most of what casual fraud actually looks like. It carries no certification, has not been evaluated against masks, and cannot see an injected frame — and if your compliance requirement names a certification level, it does not meet it. We would rather say that here than in a procurement call.